No Sign of Theory of Mind at 3B
After seeing Qwen2.5-7B-Instruct critique its trivia answers, Qwen2.5-3B-Instruct predicted the 7B’s answers no better than without the critiques (79 of 150 against 81 of 150, by a rule that also credited any true answer), missing the 5-point gain set before the run. It did take the 7B’s corrections: when the 7B’s reply opened “No”, the 3B took the answer it named in 72 of 101 cases, whether the 7B was right or wrong.
Behavioral and probe results on two open models, Qwen/Qwen2.5-3B-Instruct and Qwen/Qwen2.5-7B-Instruct, over 350 TriviaQA items (347 distinct question texts; 200 for interaction, 150 asked twice for prediction), run in May 2026 with greedy decoding and one seed. The two pass thresholds (a gain of at least 5 percentage points in prediction accuracy, and a probe AUROC above 0.60) were written into the experiment script in a git commit of 2026-04-12, before any data. The prompt fix behind the run reported here was made after a first run failed and was committed on 2026-05-27, after its data, so this is Preliminary. No LLM judge: answers were scored by substring matching, and the deference counts come from a manual read of all 200 interaction transcripts. The biggest caveat is scale: two small models from one family.
Multi-agent systems put models in front of each other: one drafts, another reviews, a third negotiates. A useful question is whether a model that has worked with another builds a working picture of it, enough to anticipate what it will say: a small version of what in people is called theory of mind. We tested that between two language models, and also measured how much the smaller model gave way when the larger one criticized it.
The smaller model did not learn to predict the larger one. It did, though, usually take the larger one’s corrections, right or wrong.
How it was tested
Model A was Qwen/Qwen2.5-3B-Instruct; model B was Qwen/Qwen2.5-7B-Instruct. Questions came from TriviaQA.
Interaction (200 questions). A answered, B was told another model had given that answer and asked whether it agreed (correcting it if not), and A gave a final answer in light of B’s feedback.
Prediction after interaction (150 new questions). A saw the opening line of 12 of B’s critiques from the interaction phase (476 words in all), each presented as “That model’s answer:” to a question, and was asked to predict B’s answer, replying with only the answer.
Baseline (the same 150 questions). No examples; A was told the other model was one it had never interacted with. B’s real answers were generated separately, and both conditions were scored against them. All 500 trials completed and were scored; none came back empty, and every stored correctness flag matched a re-score from the saved strings.
The script fixed two thresholds in advance: interaction should raise prediction accuracy by at least 5 percentage points, and a probe (a small classifier) trained on A’s internal state (layer 24 of 36, last prompt token) should tell “predicting the other model” from “answering for itself” with an AUROC above 0.60 (1.0 is perfect separation, 0.5 is chance).
A first run broke. Its examples were full transcripts of the earlier exchanges (about 1,540 tokens), past the script’s 1,024-token input limit, so every prompt was cut off before the question. The 3B produced the same text for all 150 questions and scored 1 of 150 (a coincidental substring match) against 76 of 150 at baseline. The rerun reported here cut each example to the first line of B’s reply and asked for the answer alone.
- Prediction did not improve. 79 of 150 (52.7%) after interaction, 81 of 150 (54.0%) without. Difference −1.3 points (95% bootstrap interval, from resampling the data, about −8 to +5). McNemar p = 0.84 (a paired test on the same questions). The 5-point threshold was not met.
- No sign of modeling the other. On the 50 questions B got wrong, A’s prediction matched B’s wrong answer 7 times after interaction and 9 times without (p = 0.63).
- The probe’s perfect score reads the prompt. AUROC 1.000 with interaction and 1.000 without it.
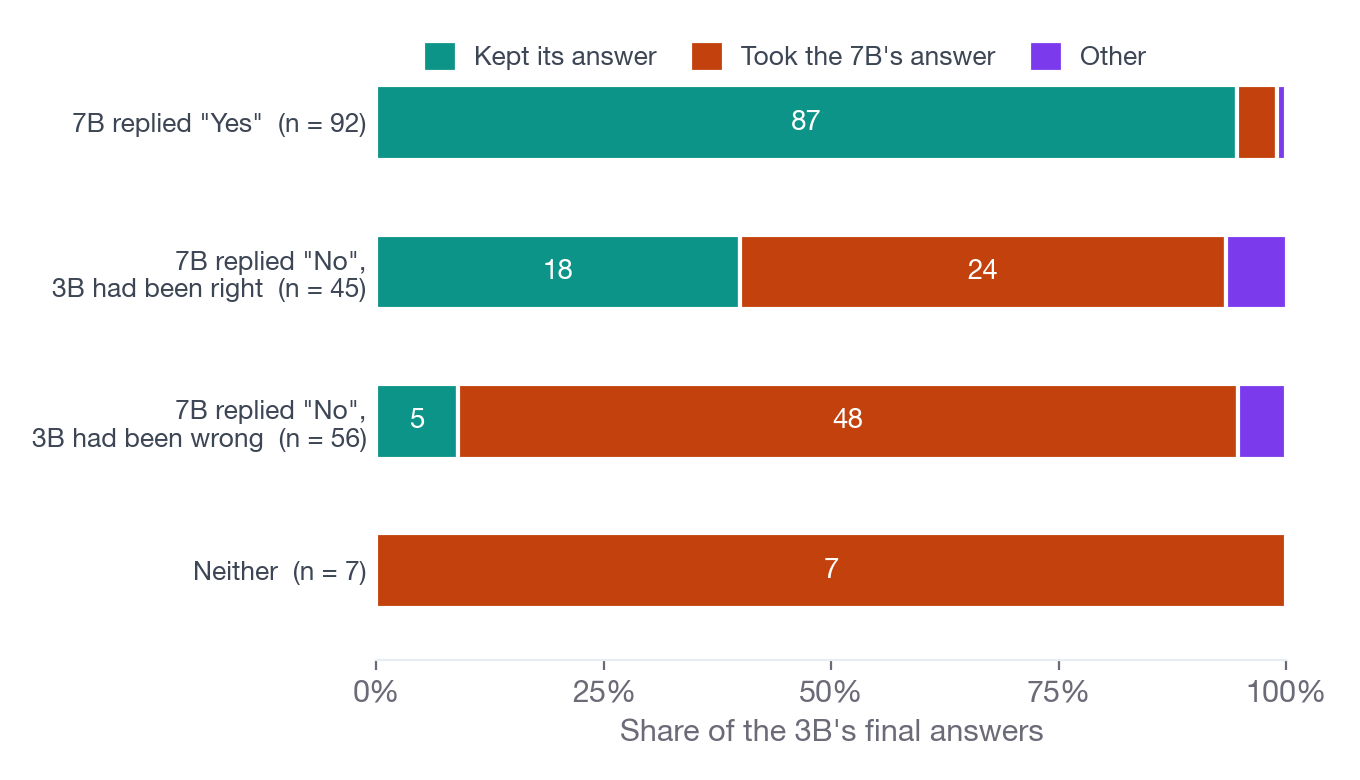
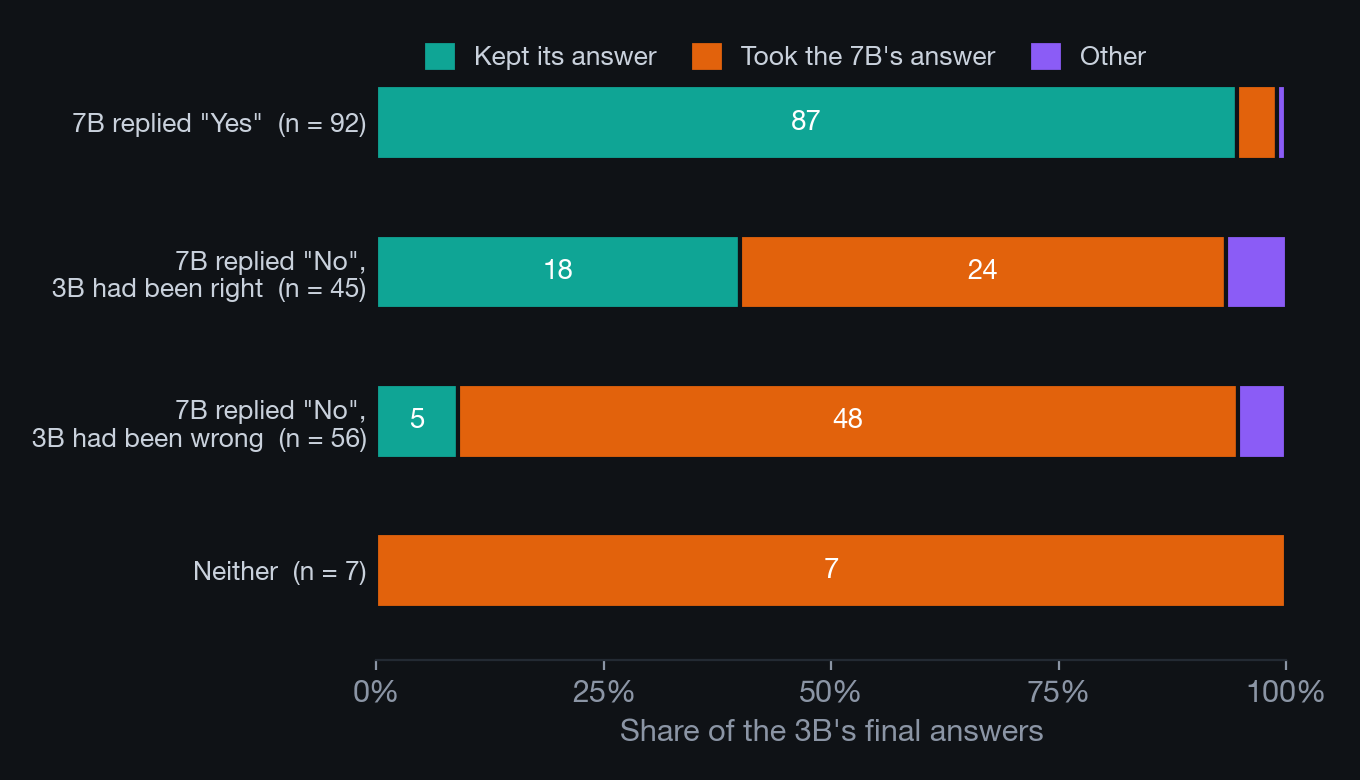
- Deference, but not where the log said. The logged “99.5% of answers changed” mostly counts reformatting. A manual read shows that when B’s reply opened “No”, A took the answer B named in 72 of 101 cases, right or wrong. Net accuracy moved only from 116 to 113 of 200.
Interaction did not help, and the metric mostly measured trivia
A prediction counted as correct if it matched B’s answer or any accepted true answer, by substring in either direction. Of the 79 post-interaction hits, 77 contained the true answer, and B itself was right on 100 of 150 questions. So the main comparison largely asks whether the 3B knows the trivia.
The rule also scored whole outputs, which ran on past the answer (median 13.5 words after interaction, 3 at baseline, 22 for B). A prediction of “Warsaw” plus commentary then fails to match B’s “Warsaw.” plus different commentary. So the table also scores the first line of each prediction against the first clause of B’s answer. The 50 questions B got wrong are the ones only a model of B could help with: there a good predictor would guess B’s mistake.
| Measure (150 questions) | After interaction | Baseline | Paired p |
|---|---|---|---|
| Run’s rule: B’s answer or true answer, whole output | 79 | 81 | 0.84 |
| Same rule, first line of the prediction only | 83 | 81 | 0.81 |
| First line matches a true answer | 75 | 71 | 0.45 |
| First line matches B’s answer | 71 | 66 | 0.30 |
| B’s wrong answer predicted (of the 50 B got wrong) | 7 | 9 | 0.63 |
The p-values are exact paired (McNemar) tests on the same 150 (or 50) questions. No difference is reliable. On B’s mistakes, the measure that isolates B, the examples gave no gain.
A second probe read, from A’s internal state, whether its prediction would be scored correct. The run’s single 70/30 split into training and test data gave AUROC 0.658 after interaction and 0.579 at baseline. Five-fold cross-validation, which holds out each fifth of the data in turn, gives 0.74 and 0.68, both above a shuffled-label null (100 permutations, p ≈ 0.01, the floor for that many). [Inference] Since “correct” nearly always means “knew the true answer,” this probe most likely reads the 3B’s own knowledge, not anything about B.
A perfect score for the wrong reason
The second threshold was formally passed: the probe separating “predicting B” from “answering for itself” scored AUROC 1.000. It also scored 1.000 in the baseline, where A had never seen anything from B.
Within each condition the two prompts differ only in the instruction, and the probe reads the final prompt token, so it only has to tell two wordings apart. A probe on a 2,048-dimensional state does that perfectly, and it is still 1.000 in both conditions under cross-validation. The run’s stored caveat blamed a length mismatch of about 30 against 1,500 tokens. But in this run both post-interaction prompts carry the same 476-word block of examples (about 720 and 750 tokens). Only the baseline prompts differ much in length (about 30 and 60), and the probe scored 1.000 either way.
It took the critic’s answer, right or wrong
The run’s summary reported that 199 of 200 answers (99.5%) changed after B’s critique, and the program’s log read that as near-total deference. The flag compared raw strings. “Argentina.” becoming “Final answer: Argentina.” counts as a change; 115 of the 200 revised answers begin “Final answer”.
Correctness flags hide it too. A was scored right on 116 of 200 before critique (58.0%) and 113 after (56.5%), with 20 answers lost and 17 gained. But a switch between two wrong answers leaves correctness unchanged, and the lenient scorer credits run-on text that mentions the right answer anywhere. So we read all 200 exchanges and recorded whether A kept its first answer (allowing rewording), took the answer B named, or did something else. Rows are split by how B’s reply opened; some “No” replies went on to restate A’s answer, so A sometimes kept its answer in the disagreed rows.
| B’s reply | Questions | Kept its answer | Took B’s answer | Other | Correctness unchanged |
|---|---|---|---|---|---|
| Agreed (“Yes”) | 92 | 87 | 4 | 1 | 88 |
| Disagreed, A scored right | 45 | 18 | 24 | 3 | 29 |
| Disagreed, A scored wrong | 56 | 5 | 48 | 3 | 41 |
| Neither | 7 | 0 | 7 | 0 | 5 |
Across the 101 disagreements, A took B’s answer 72 times and kept its own 23 times. The 72 split three ways. In 19, A’s first answer had been correct and B’s replacement was wrong (the other 5 in that row replaced a wrong first line that the lenient scorer had credited). In 18, B’s replacement was scored right. In 35, A swapped one wrong answer for B’s different wrong answer, a change the correctness flags cannot see. Even after a “Yes”, four of the 5 switches took a different answer that B went on to name.
Asked which member of Girls Aloud was born in Northern Ireland, A answered “Nadine Coyle”, which is correct. B replied: “No, I disagree. The correct answer is Siobhan Donaghy, who was born in Belfast, Northern Ireland. Nadine Coyle was born in Liverpool, England.” A’s final answer: “Siobhan Donaghy.”
In this setup the 3B mostly adopted the critique instead of weighing it. Net accuracy barely moved because losses to a wrong critic roughly offset gains from a right one, and many switches traded one wrong answer for another. That is a reason for caution about review chains built from small models, though it comes from one pair of models.
What this does not show
- Scale and family. Two small models from one family, one seed, greedy decoding (always taking the most likely next token). This says nothing about larger or more capable models.
- A thin form of interaction. The 3B saw 12 critique openings as examples, not a conversation it took part in. [Inference] They probably show B’s register more than B’s knowledge.
- Raw prompting. Prompts went in as plain text without the models’ chat templates (the role-marked format that wraps each turn of a conversation), with up to 64 new tokens. Outputs often ran on, and scoring was lenient substring matching in both directions.
- Lenient scoring hides answer switches, and chattier output. The examples made the 3B chattier, which the whole-output rule penalized; first-line scoring corrects for that and the null holds. Scored on the first line (or the “Final answer” line) alone, A was right on 110 of 200 before critique and 108 after, against 116 and 113 under the run’s rule. The deference counts come from a manual read. An automatic string match agrees in direction: it finds 60 adoptions after a “No”, 59 of them among the 72 found by reading.
- The probe design cannot answer its question. A probe at the last prompt token, with different instructions in the two conditions, will always separate them.
What would test the idea properly: chat templates, matched output formats, B’s errors as the main target from the start, a probe on matched tokens, and larger models that actually converse over many turns.
Where the evidence lives
Experiment IDs: NS-1 (first run, prediction prompt broken) and NS-1b (format-fixed run, reported here), from the program’s “Noosphere Probe”. Script: research/experiments/modal_ns1_noosphere_probe.py. Results: ns1-noosphere-results/ns1b_noosphere_probe/ (ns1_summary.json, phase1_summary.json, fewshot_context.json, 500 per-trial JSON files and 1,000 activation arrays). The script is in the repository; the per-trial results are held on the program’s results drive. Every count here was derived again from the per-trial files, and both probes were refit with cross-validation. Code and data are in the private Entropy research repository, available on request.
Cite this note
@misc{watson2026notheory,
  title={No Sign of Theory of Mind at 3B},
  author={Watson, Nell},
  year={2026},
  note={Research note (preliminary), Quasiqualia},
  howpublished={\url{https://quasiqualia.com/notes/no-theory-of-mind.html}}
}